Prepared by: Openzeka Teknoloji A.Ş. — Official Embedded Compute Distributor for NVIDIA Türkiye & MEA, and NVIDIA Elite Partner
Test platform: 4× NVIDIA DGX Spark (GB10) · Model: DeepSeek-V4.1-Flash (763B) · Report date: September 2026
Contents
- 1. Introduction
- 2. Model Architecture
- 3. Hardware
- 4. vLLM Build and Patch Chain
- 5. Configuration
- 6. Performance Results
- 7. Comparative Analysis
- 8. SLO and Capacity
- 9. Conclusion
- Appendix A: Docker Image Build Instructions
- Appendix B: Engram Row Ranges
- Appendix C: Verification Commands
1. Introduction
DeepSeek-V4.1-Flash is a multimodal Mixture-of-Experts (MoE) model with 552B backbone parameters. Its Hugging Face checkpoint contains 763B parameters (552B backbone + 196B Engram conditional memory + vision encoder). The model ships with FP8 (F8_E4M3) weight quantization and FP4 (E2M1) KV cache, and supports contexts of up to one million tokens.
This report documents the deployment of this model on 4× NVIDIA DGX Spark (GB10) using tensor parallelism (TP=4). DGX Spark is an office-friendly mini supercomputer with 128 GB unified LPDDR5X memory and 273 GB/s bandwidth — approximately 1/30th the bandwidth of data center GPUs (~8 TB/s HBM3e). Running a 763B data center model on this hardware is made possible by multi-node Ethernet tensor parallelism and the Engram-on-disk technique.
Two aspects make this work worth documenting:
- The model is data center class. DeepSeek-V4.1-Flash is normally served on DGX-B300 / GB300 NVL72 hardware. 4× DGX Spark represents the scalable edge of the architecture.
- 7 SM 12.1-specific patches. The stock vLLM nightly image has missing or broken code paths for SM 12.1a (GB10) — Engram-on-disk, FlashInfer sparse attention, SWA block size, attention page sizes — which are fixed with community patches.
This is a deployment guide, not a benchmark comparison. Benchmark results are presented in Section 6, but limited to 4 data points — sufficient to characterize the hardware class but not for comprehensive SLO/capacity analysis. For that, see the Qwen3.6-27B DGX Spark Cluster Scaling report.
2. Model Architecture
2.1 Overview
DeepSeek-V4.1-Flash introduces an architecture that dramatically reduces the KV cache footprint. Key specifications:
| Component | Value |
|---|---|
| Backbone parameters | 552B |
| Total checkpoint parameters | 763B (HF verified) |
| Active parameters per token (prefill) | 8B |
| Active parameters per token (decode) | 16B |
| Engram conditional memory | 196B (sparsely accessed via token-based lookup) |
| Shared / routed experts | 1 / 384 (6 active per token) |
| Maximum context | 1,000,000 tokens |
| Weight quantization | FP8 (F8_E4M3, in checkpoint) |
| KV cache quantization | FP4 (E2M1, runtime — CSA2 architectural feature) |
| Checkpoint size | 476 GB (120 safetensors blobs — below theoretical 763 GB due to MoE structure and mixed precision) |
2.2 Causal Encoder-Decoder (CED) Architecture
The model is a 40-layer Transformer organized as a 20-layer causal encoder followed by a 20-layer decoder. The key advantage of CED: the decoder’s global KV cache is projected from the encoder’s final hidden states rather than derived from each decoder layer’s own hidden states. This allows activating only 8B parameters during prefill and 16B during decode — significant cost efficiency for input-heavy agentic workloads.
SWA Bounded Replay reconstructs missing Sliding Window Attention (SWA) KV states by replaying only the most recent n_win tokens, avoiding the need to persist SWA KV to SSD. This reduces the persistent KV cache footprint to roughly 1/8 of that of DeepSeek-V4-Flash.
2.3 Compressed Sparse Attention 2 (CSA2)
CSA2 assigns each attention layer one of three static modes — Full, Reindex, or Reuse — to share main KV and indexer K across layers and reuse Top-K sparse-attention indices. In the decoder, a Hierarchical Sparse Indexer further restricts later indexing layers to a candidate pool constructed by the first Full Mode layer, bounding deeper indexer cost independently of context length.
Combined with FP4 main KV caching (E2M1 format, one E4M3 scale per 16 channels), these designs reduce the global KV cache footprint to 890 bytes per token — roughly 1/4 of DeepSeek-V4-Flash.
2.4 Engram Conditional Memory
The 196B Engram layer is sparsely accessed via token-based lookup. This deployment uses Engram-on-disk mode: Engram rows are stored on each node’s local disk rather than in GPU memory, and staged into GPU memory on demand. This enables the 763B model to fit within 4× 128 GB (512 GB total) unified memory.
2.5 DSpark Speculative Decoding
DSpark is a speculative decoding mechanism using semi-autoregressive draft generation with confidence-scheduled verification. This deployment uses k=5 depth — 5 tokens are predicted ahead and verified at each decode step. Verified tokens are appended to the output; rejected ones are regenerated.
3. Hardware
| Component | Value |
|---|---|
| GPU | Blackwell architecture (GB10), SM 12.1 (CC 12.1), 48 SMs |
| GPU memory | 128 GB unified LPDDR5X (shared CPU+GPU) |
| Memory bandwidth | ~273 GB/s (unified) |
| FP4 peak (with sparsity) | ~1 PFLOP |
| CPU | 20-core Arm (10× Cortex-X925 + 10× Cortex-A725) |
| Node interconnect | NVIDIA ConnectX-7, 200 Gb/s RDMA (QSFP) |
Critical architectural fact: There is no NVLink between DGX Sparks. TP=4 in this deployment is multi-node tensor parallelism over a ConnectX-7 200 GbE network — every all-reduce operation crosses the Ethernet fabric.
4. vLLM Build and Patch Chain
The stock vLLM nightly image has missing code paths for SM 12.1a (GB10) in the DeepSeek-V4.1-Flash code paths. This section documents the build chain and 7 patches applied to create the custom Docker image (vllm-dsv41:latest, 33.8 GB).
4.1 Base Image and vLLM Branch
- Base image:
vllm/vllm-openai:nightly-8a728663c1c3eeace834a95f5654fa653cc1998c - vLLM branch: Checked out via
build/fetch_vllm_branch.sh, commite47aa780b - Source repo: tonyd2wild/DeepSeek-V4.1-Flash-vLLM-DGX-Spark (boot10 config)
4.2 Overlay Build Chain
The build consists of 5 overlay layers and a patch layer. Each overlay builds on top of the previous one:
| Step | Name | Content |
|---|---|---|
| 1 | C extension | _C_stable_libtorch + _moe_C_stable_libtorch — compiled for SM 12.1a (build_stable_ext.sh in v41build container) |
| 2 | overlay1 | Base image + vLLM branch tree (vllm/vllm/) + 2 .so files |
| 3 | overlay3 | FlashInfer 0.7.0rc1 (07869c61) compiled |
| 4 | overlay4 | CUTLASS mxfp8_gemm_sm120 prebuilt (MAX_JOBS=4) |
| 5 | overlay5 | sparse_mla_sm120 prebuilt + verify (HIT/HIT) |
| 6 | patch layer | 7 patch files baked into image + ENTRYPOINT [] added |
Important: The Dockerfile must use
COPY vllm/vllm/(notvllm/) —vllm/is a git repo, the Python package is undervllm/vllm/.
4.3 Patches
The following 7 patches are baked into the image:
| # | File | Mount path | Function |
|---|---|---|---|
| 1 | engram.py |
models/deepseek_v4_1/common/engram.py |
Engram-on-disk, rank-offset fix |
| 2 | model_state.py |
models/deepseek_v4_1/nvidia/model_state.py |
Engram staging before forward (CUDA graph safe) |
| 3 | weight_utils.py |
model_executor/model_loader/weight_utils.py |
Skip Engram tables on load |
| 4 | attention.py |
models/deepseek_v4_1/attention.py |
SM 12.1 page sizes |
| 5 | flashinfer_sparse.py |
models/deepseek_v4_1/nvidia/flashinfer_sparse.py |
64-state pages |
| 6 | sparse_swa.py |
v1/attention/backends/mla/sparse_swa.py |
SWA block size hook |
| 7 | sparse_attn_indexer.py |
model_executor/layers/sparse_attn_indexer.py |
SM 12.1 top_k_per_row_decode |
4.4 Optimizations
- OMP_NUM_THREADS=1 — added to the recipe (reduces spin-wait contention)
- GPU clock monitoring — all 4 nodes healthy (2106-2249 MHz, 85-93W, 85-88 TFLOPS)
- Build artifacts cleaned — overlay1/3/4/5, base image, build cache deleted (~258 GB reclaimed)
5. Configuration
5.1 sparkrun Recipe
The sparkrun recipe (deepseek-v41-flash-tp4.yaml) contains the following parameters:
| Parameter | Value | Description |
|---|---|---|
tensor_parallel |
4 | 4 nodes × 1 GPU |
gpu_memory_utilization |
0.80 | 80% GMU |
max_model_len |
300000 | 300K context (below 1M, memory constrained) |
max_num_seqs |
8 | Maximum 8 concurrent sequences |
max_num_batched_tokens |
8192 | Prefill batch size |
block_size |
128 | KV cache block size |
distributed-executor-backend |
mp | Multiprocess backend |
5.2 Speculative Decoding Configuration
{
  "method": "dspark",
  "num_speculative_tokens": 5,
  "draft_sample_method": "probabilistic",
  "rejection_sample_method": "block",
  "enable_adaptive_verification": false
}
With DSpark k=5 depth, 5 tokens are predicted ahead at each decode step.
5.3 Engram-on-disk Configuration
DSV41_ENGRAM_DISK=1
DSV41_ENGRAM_DISK_THREADS=32
DSV41_ENGRAM_DISK_CHUNK=16
Engram rows are stored on disk, read in parallel with 32 threads, and staged into GPU memory in chunks of 16.
5.4 Launch Command
sparkrun run /home/nvidia/.cordatus-sparkrun/recipes/deepseek-v41-flash-tp4.yaml \
  --hosts 192.168.1.153,192.168.1.147,192.168.1.166,192.168.1.148 \
  --foreground
5.5 Serving Parameters
The model is served with thinking mode disabled ("thinking": false), tool calling and multimodal (vision) support enabled:
--default-chat-template-kwargs '{"thinking": false}'--tool-call-parser deepseek_v41 --enable-auto-tool-choice--reasoning-parser deepseek_v41--limit-mm-per-prompt '{"image":4}'--compilation-configwith CUDA graphs (FULL_AND_PIECEWISEmode)
6. Performance Results
6.1 Benchmark Table
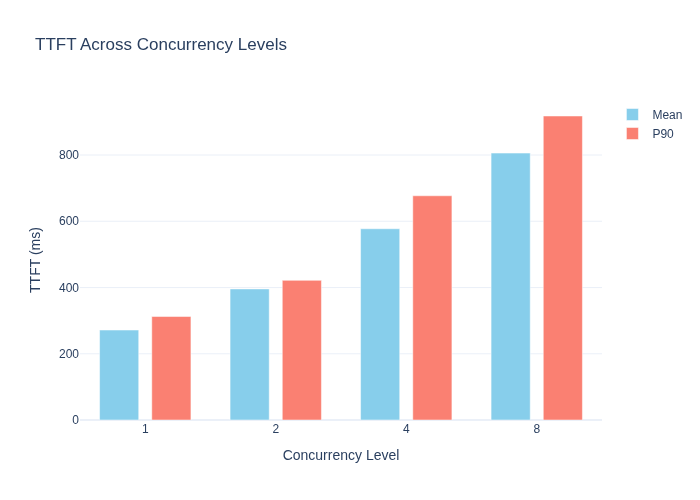
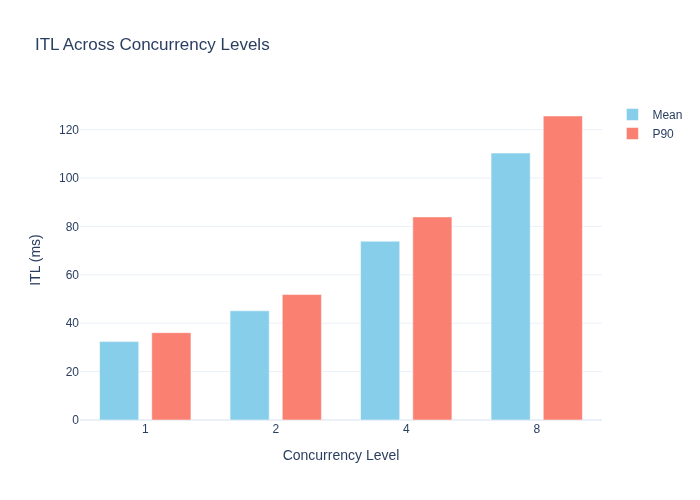
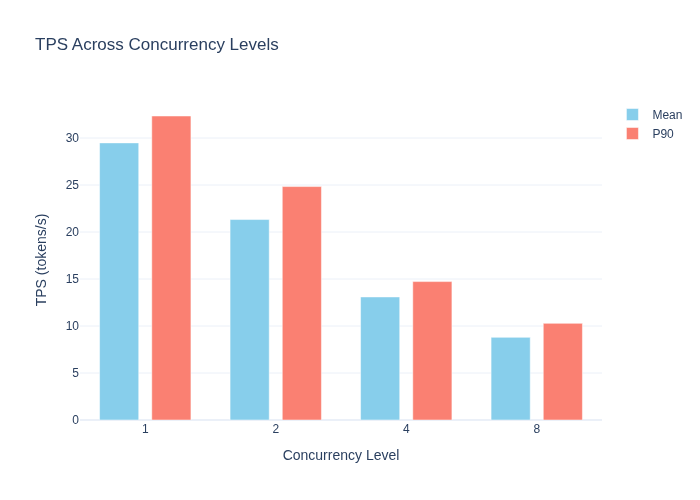
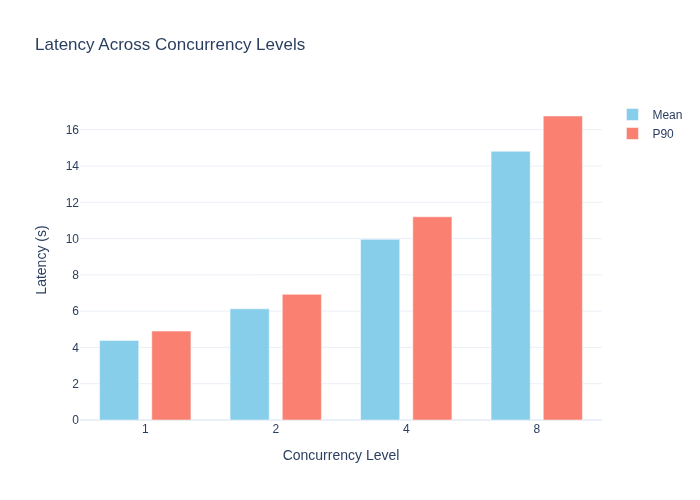
Measurements were taken with CordatusAI/llm-benchmark (2nd run, after JIT warmup).
| Concurrency | TTFT (ms) | ITL (ms) | TPS (tok/s) | Latency (s) | Throughput (RPS) |
|---|---|---|---|---|---|
| 1 | 271.63 | 32.39 | 29.48 | 4.39 | 0.23 |
| 2 | 395.75 | 45.12 | 21.32 | 6.13 | 0.16 |
| 4 | 577.41 | 73.86 | 13.09 | 9.96 | 0.10 |
| 8 | 805.89 | 110.28 | 8.79 | 14.81 | 0.07 |
6.2 Charts
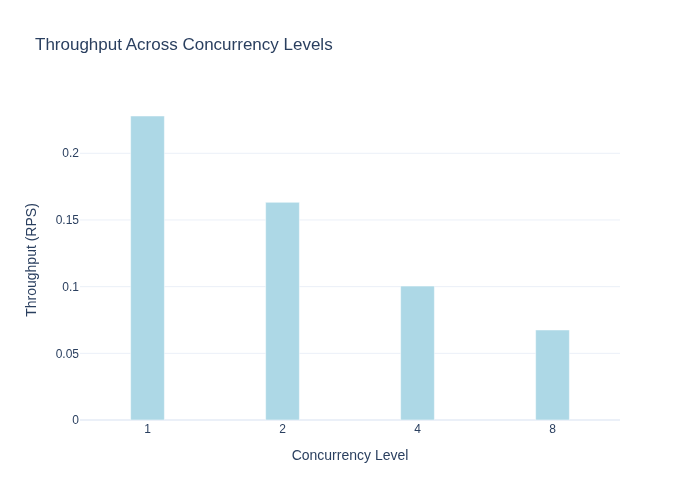
6.3 Assessment
- 29.5 tok/s at C=1 is sufficient for interactive use, above the reading speed threshold (~15 tok/s).
- TTFT rises as expected with concurrency (272→806 ms, ~3x) — prefill is compute-bound.
- TPS decline reflects growing memory bandwidth contention as the GPU approaches saturation (29.5→8.8 tok/s, ~70% drop).
- Max C = 2 at the Benchmark Explorer’s default targets (TTFT≤1000ms, TPS≥15) — chat capacity 2, agentic capacity 1.
6.4 DSpark Acceptance
The effectiveness of DSpark speculative decoding is measured by acceptance ratio and draft rate:
| Prompt type | Mean acceptance | Draft rate |
|---|---|---|
| Prose (bench) | 2.1–2.3 | 22% |
| Coding | 4.9–5.3 | 80–86% |
Source repo (boot10 config) test average: 3.57 acceptance, 60% draft rate (8-category average). The high acceptance of DSpark k=5 on coding prompts (4.9-5.3 / 5) reflects the repetitive structure of code.
7. Comparative Analysis
7.1 Comparison with DGX-B300
DeepSeek-V4.1-Flash has also been measured on the LLM Inference Benchmark Explorer on DGX-B300 (8× Blackwell Ultra, TP=4). The B300 row serves the same model with different parameters: DSpark k=3 (instead of the k=5 used here), 1M context (instead of 300K), and FP8 quantization.
| Concurrency | 4× Spark TP4 TPS | B300 TP4 TPS | Ratio |
|---|---|---|---|
| 1 | 29.48 | 284.54 | 9.65× |
| 2 | 21.32 | 294.56 | 13.82× |
| 4 | 13.09 | 252.60 | 19.30× |
| 8 | 8.79 | 209.41 | 23.83× |
B300 is ~9.65× faster at C=1. This gap is expected and stems from the fundamental difference between the two hardware classes:
| Feature | DGX-B300 | 4× DGX Spark |
|---|---|---|
| GPU memory | HBM3e (~8 TB/s) | LPDDR5X unified (273 GB/s) |
| Memory bandwidth ratio | 1× | ~1/30 |
| GPU interconnect | NVLink | ConnectX-7 200 GbE RDMA |
| SMs per GPU | 148 (B200) | 48 (GB10) |
| FP4 peak | ~9 PFLOP | ~1 PFLOP |
Conclusion: 4× DGX Spark can run a 763B data center model — but it does not replace data center hardware. This configuration is suitable for development, prototyping, and limited-user production scenarios.
8. SLO and Capacity
At the Benchmark Explorer’s default targets (TTFT≤1000ms, TPS≥15 tok/s), this configuration yields Max C = 2:
| SLO | Threshold | C=2 status |
|---|---|---|
| TTFT | ≤ 1000 ms | 396 ms ✓ |
| TPS | ≥ 15 tok/s | 21.32 tok/s ✓ |
Warning: At C=4, TPS drops to 13.09, falling below the 15 tok/s threshold. For interactive chat services, 1-2 concurrent users are recommended; for higher loads, data center hardware (B300/GB300) should be preferred.
9. Conclusion
- DeepSeek-V4.1-Flash (763B) can run on 4× DGX Spark — demonstrating the scalability ceiling of office-friendly mini supercomputers.
- 7 SM 12.1 patches are mandatory — the stock vLLM nightly image has missing code paths for GB10 (SM 12.1a) in Engram-on-disk, FlashInfer sparse attention, and SWA paths.
- Engram-on-disk enables the model to fit in memory — offloading the 196B conditional memory to disk allows the 763B model to fit within 512 GB total unified memory.
- DSpark k=5 is effective on coding prompts with 80-86% draft rate; on prose prompts, this drops to 22%.
- 29.5 tok/s at C=1 is sufficient for development and prototyping; for production serving, B300-class hardware is ~10× faster.
- This configuration is a development platform, not a data center alternative. The ability to run a 763B model on office hardware demonstrates the boundaries of edge and on-premises deployment.
Appendix A: Docker Image Build Instructions
This appendix contains full instructions to build the vllm-dsv41:latest image from scratch. All commands are run on the head node (192.168.1.153).
A.1 Clone the Repo
cd /home/nvidia
git clone https://github.com/tonyd2wild/DeepSeek-V4.1-Flash-vLLM-DGX-Spark.git
cd DeepSeek-V4.1-Flash-vLLM-DGX-Spark
A.2 Checkout vLLM Branch
bash build/fetch_vllm_branch.sh /home/nvidia/vllm
# commit e47aa780b
rm -f vllm && cp -a /home/nvidia/vllm ./vllm
A.3 Build C Extensions
docker run -d --name v41build --gpus all --network host --entrypoint sleep \
  -v /tmp/v41build-src:/src vllm/vllm-openai:nightly-8a728663c1c3eeace834a95f5654fa653cc1998c 7200
docker exec v41build pip install cmake ninja -q
bash build/build_stable_ext.sh
docker cp v41build:/src/build/_C_stable_libtorch.abi3.so build/
docker cp v41build:/src/build/_moe_C_stable_libtorch.abi3.so build/
A.4 Overlay Chain
# overlay1: base + vLLM tree + 2 .so files
docker build -t vllm-dsv41:overlay1 -f build/Dockerfile.overlay1 .

# overlay3: FlashInfer 0.7.0rc1
bash build/build_overlay3.sh

# overlay4: CUTLASS mxfp8_gemm_sm120
bash build/build_overlay4.sh

# overlay5: sparse_mla_sm120 + verify
cp build/prewarm5.py build/verify5.py /tmp/
bash build/build_overlay5.sh
A.5 Patch Layer
FROM vllm-dsv41:overlay5
COPY DeepSeek-V4.1-Flash-vLLM-DGX-Spark/patch/engram.py /usr/local/lib/python3.12/dist-packages/vllm/models/deepseek_v4_1/common/engram.py
COPY DeepSeek-V4.1-Flash-vLLM-DGX-Spark/patch/model_state.py /usr/local/lib/python3.12/dist-packages/vllm/models/deepseek_v4_1/nvidia/model_state.py
COPY DeepSeek-V4.1-Flash-vLLM-DGX-Spark/patch/weight_utils.py /usr/local/lib/python3.12/dist-packages/vllm/model_executor/model_loader/weight_utils.py
COPY DeepSeek-V4.1-Flash-vLLM-DGX-Spark/patch/attention.py /usr/local/lib/python3.12/dist-packages/vllm/models/deepseek_v4_1/attention.py
COPY DeepSeek-V4.1-Flash-vLLM-DGX-Spark/patch/flashinfer_sparse.py /usr/local/lib/python3.12/dist-packages/vllm/models/deepseek_v4_1/nvidia/flashinfer_sparse.py
COPY DeepSeek-V4.1-Flash-vLLM-DGX-Spark/patch/sparse_swa.py /usr/local/lib/python3.12/dist-packages/vllm/v1/attention/backends/mla/sparse_swa.py
COPY DeepSeek-V4.1-Flash-vLLM-DGX-Spark/patch/sparse_attn_indexer.py /usr/local/lib/python3.12/dist-packages/vllm/model_executor/layers/sparse_attn_indexer.py
ENTRYPOINT []
cd /home/nvidia && docker build -t vllm-dsv41:latest -f Dockerfile.patches .
A.6 Worker Distribution
sparkrun auto-distributes the image, but if manual distribution is needed:
docker save vllm-dsv41:latest | ssh nvidia@192.168.1.147 docker load
docker save vllm-dsv41:latest | ssh nvidia@192.168.1.166 docker load
docker save vllm-dsv41:latest | ssh nvidia@192.168.1.148 docker load
Appendix B: Engram Row Ranges
In Engram-on-disk mode, each rank (node) holds different row ranges on its local disk:
| Rank | Node | Layer 1 Rows | Layer 14 Rows |
|---|---|---|---|
| 0 | 153 (head) | [0, 96000564) | [0, 96003054) |
| 1 | 147 | [96000564, 192001740) | [96003054, 192007016) |
| 2 | 166 | [192001740, 288003654) | [192007016, 288011564) |
| 3 | 148 | [288003654, 384006168) | [288011564, 384016682) |
A total of ~384M rows, evenly split across 4 ranks.
Appendix C: Verification Commands
API Health
curl http://192.168.1.153:8000/v1/models
Simple Test
curl http://192.168.1.153:8000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{"model":"deepseek-v4.1-flash","max_tokens":50,
       "messages":[{"role":"user","content":"Count from 1 to 10."}]}'
Openzeka Teknoloji A.Ş. — openzeka.com · Tel: +90 312 266 2055
Üniversiteler Mah. Şehit Mustafa Tayyarcan Cad. Tepe Binası No:5 İç Kapı No:315, 06800 Çankaya/Ankara, Türkiye
This report was generated from measurements produced with the CordatusAI/llm-benchmark tool. Deployment recipe adapted from tonyd2wild/DeepSeek-V4.1-Flash-vLLM-DGX-Spark boot10 config. Report date: September 2026